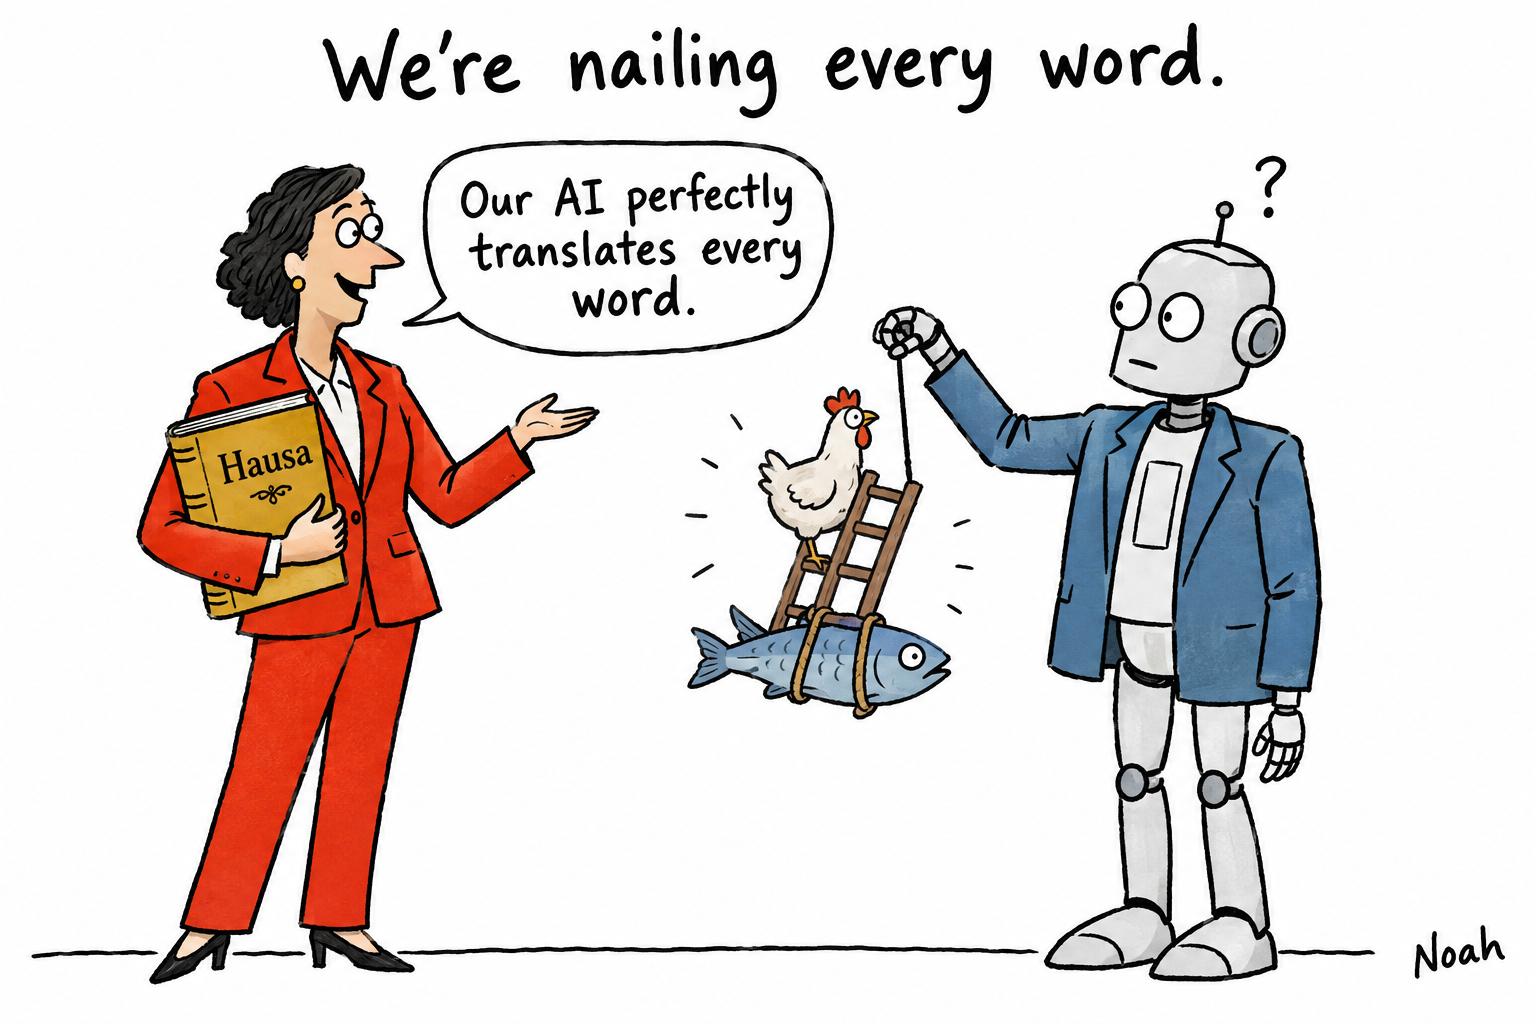
In newsrooms increasingly tempted to lean on artificial intelligence for translation and verification, Hausa remains a sharp reminder that fluent-looking output can still be badly wrong. The core problem, as Legit.ng’s head of the Hausa desk Salisu Ibrahim argues, is not simply that machines misread words; it is that they miss the cultural logic that gives those words meaning. A phrase, a proverb or a praise chant can easily be flattened into a hostile or misleading label when the system has no grasp of local idiom, social context or rhetorical convention. Research on Hausa NLP has long pointed to the same structural weakness: the language is still under-resourced, with too little annotated data and too little model support for reliable automated handling.
That matters because Hausa is not a marginal language. It is spoken by more than 100 million people across West Africa, yet it remains poorly represented in the datasets that shape moderation, translation and fact-checking tools. The result is a predictable pattern: systems trained mainly on English tend to misclassify Hausa posts, particularly when they rely on idiom, metaphor or political allusion. Hausa AI Studio has argued that this remains a live quality-control problem, and in July 2026 it said benchmarking of leading models still produced errors within ten prompts, underlining how fragile current performance remains.
Ibrahim’s article uses Hausa rhetorical forms to show why literal reading is so dangerous. Karin magana, the language’s proverb tradition, often encodes meaning indirectly, while habaici, or innuendo, can carry criticism that appears harmless to an outsider. Kirari, the praise-poetry tradition, can sound like bravado or even violence to an automated system even when it is simply honouring a person or cause. That cultural depth is precisely what general-purpose tools struggle to detect, and it helps explain why researchers working on offensive Hausa datasets have stressed the difficulty of distinguishing banter, coded insult and genuine threat. The weakness is not confined to translation quality; it goes to the heart of whether the machine understands what kind of speech it is reading.
The editorial risk is heightened by the confidence with which these systems answer. As Legit.ng notes, a tool that does not know it is uncertain can prompt editors to act on a false classification as though it were settled fact. That danger becomes larger in a media environment where many users already treat AI-generated summaries as fact-checks. The article points to previous public examples in Nigeria and elsewhere in which automated tools misread events, mislabelled content or failed to recognise the context in which a post appeared. This is not just a technical limitation; it is a newsroom governance problem, because a confident wrong answer can shape publication decisions, takedowns or accusations before a human expert has intervened.
There are also broader platform consequences. Automated translation is often used in moderation systems, but poor Hausa handling can lead to either wrongful removal of legitimate speech or the failure to detect harmful material. The article cites cases in which extremist or misleading content in African languages circulated because systems did not parse it properly, a risk that academic work on Hausa NLP has repeatedly linked to limited training data and weak language representation. In parallel, the wider African AI market is beginning to respond: TechRadar recently reported on MORENA, a 1.5 billion-parameter model from Vambo AI built for 12 African languages, including Hausa, as evidence that more tailored systems may outperform larger general-purpose ones. Even so, the article’s underlying point stands: better tools are emerging, but newsroom practice is still lagging behind the reality of linguistic complexity.
The practical response, Ibrahim argues, is to slow down before deploying AI on Hausa content. That means insisting on human sign-off from Hausa-speaking editors, using native speakers in annotation and calibration, testing tools against real idioms before trusting them operationally, and setting uncertainty thresholds so low-confidence outputs are escalated rather than treated as final. It also means logging human overrides so repeated failure patterns can be identified, and supporting broader data-building efforts rather than waiting for commercial platforms to solve the problem unaided. The most recent work around Hausa transcription and special-purpose quality assurance points in the same direction: specialised language support works better than generic automation. For now, the lesson for newsrooms is simple. If a tool cannot understand the language’s subtleties, it should not be allowed to decide what those subtleties mean.
Source Reference Map
Inspired by headline at: [1]
Sources by paragraph:
- Paragraph 1: [2], [3]
- Paragraph 2: [2], [3], [4]
- Paragraph 3: [2]
- Paragraph 4: [1]
- Paragraph 5: [1], [2], [5]
- Paragraph 6: [1], [2], [6], [7]
Source: Noah Wire Services